WHEN IT MAKES SENSE
When the environment grows, but the operating foundation still depends on exceptions and manual intervention
When development, staging and production no longer follow the same standard
We organize environments and configuration patterns to reduce inconsistency, deployment failure and wasted effort fixing context drift.
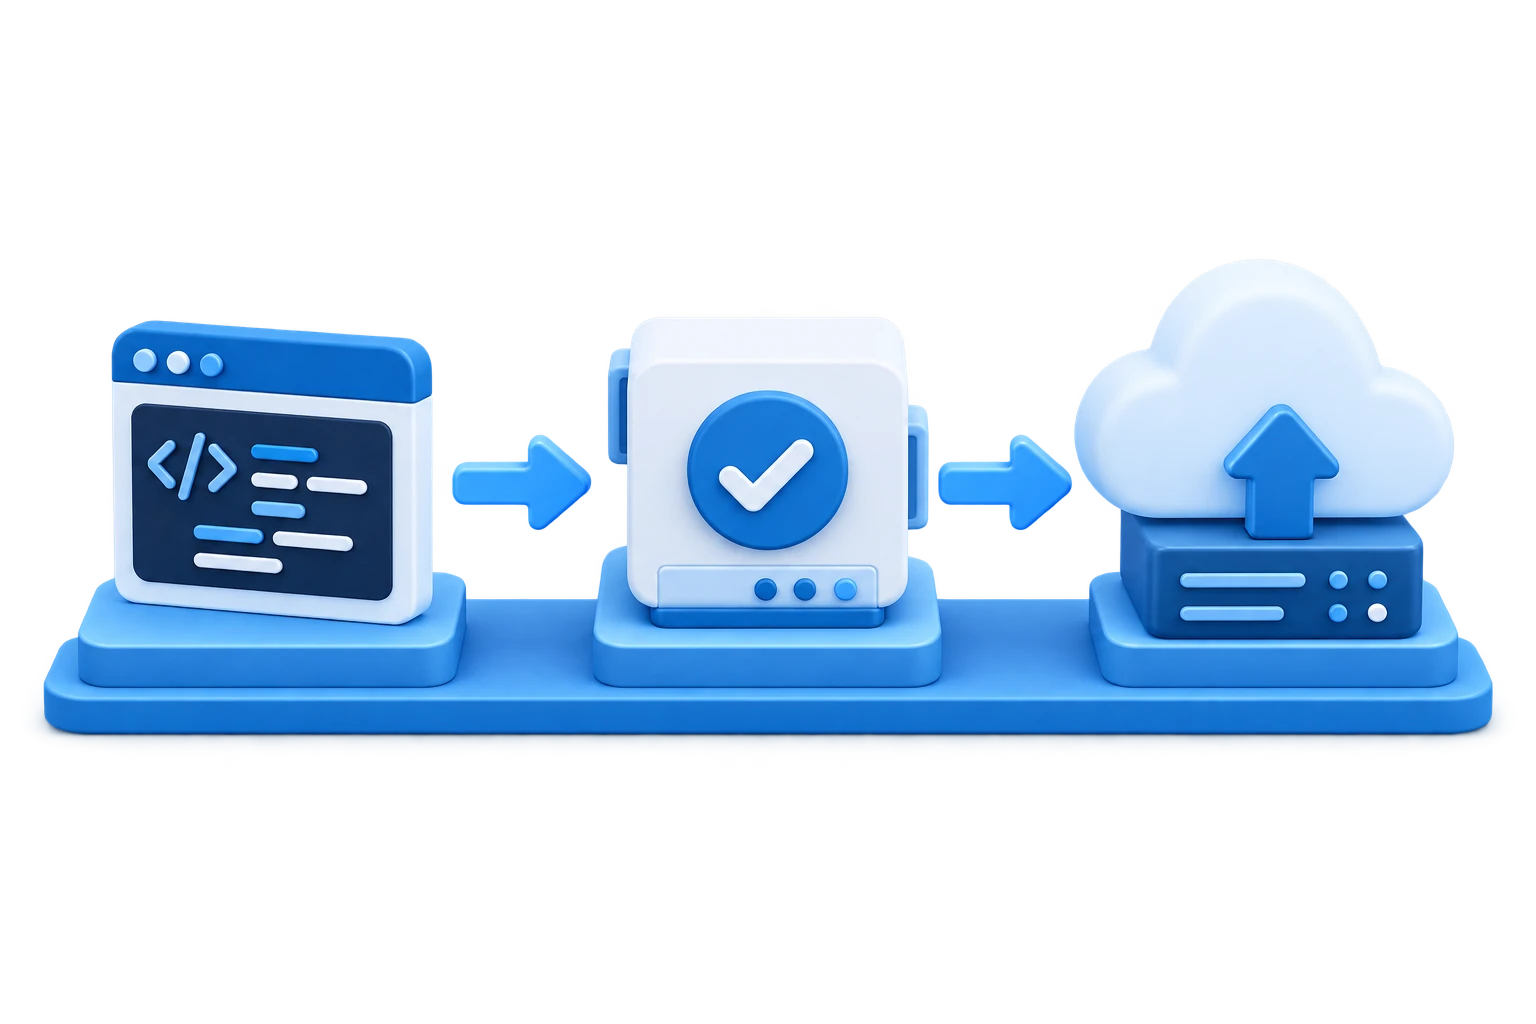
When publishing a change still depends on too many manual steps
We automate pipelines, validation and release flow to increase speed without losing operational control.
When the team needs more visibility into performance, incidents and capacity
We structure monitoring, alerts and environment visibility to support the routine with fewer surprises and slower reactions.
WHAT WE DELIVER
Cloud platform and DevOps designed for the real delivery and support routine
Cloud foundation, environments and infrastructure as code
- Base structure in AWS and Azure standardized by stage
- Repeatable provisioning with less dependency on manual adjustment
- Foundation for security, access and controlled evolution of the environment
CI/CD, release automation and change flow
- Pipelines with build, validation and promotion across environments
- More predictable and auditable deployment routines
- Less operational bottleneck on the path to production
Observability, operations support and basic governance
- Metrics, logs, alerts and operational visibility
- Incident reading, capacity awareness and workload behavior
- Foundation for continuous platform improvement
HOW WE WORK
How we turn a functional environment into a more mature platform
Assessment of the current topology, operating criticality and delivery bottlenecks
We start from the real environment, business constraints and what currently consumes the most time, risk and operating effort.
Platform structuring with standards, automation and operational criteria
We organize cloud foundation, configuration, access, pipelines and artifacts to bring more consistency to the delivery cycle.
Observability and operating routines connected to platform design
A platform has to be observable. That is why we include incident visibility, behavior analysis and capacity reading from the start.
Continuous improvement to keep delivery fast without losing stability
We evolve the platform with regular reviews of process, cost, risk and reliability, avoiding operational regression.